Skip to content
Portrait of Parham Khosh Solat

ParhamKhoshSolat

Data scientist with three years in industry, finishing an MSc in Data Science at Federico II (expected February 2027). My thesis studies how a learning robot can stay transparent and trustworthy to the person teaching it.

Open to data scientist and ML engineer roles, and to funded PhD positions in reinforcement learning and human-robot interaction.

Naples, Italy · open to relocation

data scientist at Sakoudar, an influencer marketing platform, 2022 to 2025
3 years
data scientist at Sakoudar, an influencer marketing platform, 2022 to 2025
MSc Data Science weighted average, Federico II
28.67/30
MSc Data Science weighted average, Federico II
live demos you can try on this site
4
live demos you can try on this site

Selected work

Three projects to start with

Each card opens the full write-up: the question, the method, the results and the honest limits.

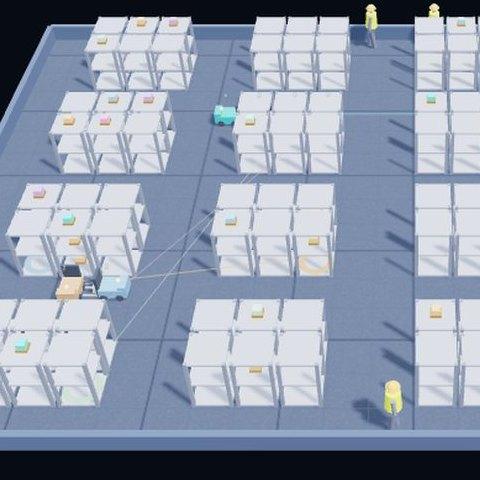
Live demo screenshot
Live demo
3.03×
greedy throughput for prioritized planning, 15 held-out task streams
Planner3.03×
Best RL2.53×
Greedy1×

Live demoSolo · course project2026

Warehouse robots: classical planners vs reinforcement learning

Six self-driving forklifts share one warehouse. I built the simulator and made nine routing methods compete under one safety layer that rules out collisions, so they compete on deliveries alone.

Limit: One simulated warehouse layout; walking workers appear in the demo only, not in the scored runs.

Read the write-up Live demo
Damaged 16.1 dB
Step 2 · 19.3 dB
Step 3 · 20.1 dB
Original
Real agent output, one held-out patch
Live demo
+2.93 dB
mean repair gain, 1,500 held-out test patches
Best tool2.34
Agent2.93
One CNN4.03

Live demoSolo · course project2026

An RL agent that repairs damaged photos

Blur, noise and JPEG damage arrive at unknown strengths. I reimplemented a CVPR 2018 method in which an agent chains up to 3 of 12 small repair networks, then added the fine-tuning step the paper never released.

Limit: A single CNN of the same size repairs more (+4.03 dB); scores are on small 63×63 test patches.

Read the write-up Live demo
Alarms · KPIs · network map
Model ranks every candidate cause
Rule check confirms
or: investigate
System outline
Private code
0 of 710
wrong causes sent as act-now, sealed simulated test
Right first497
Old ranker137
No claim213
of 710 single faults

Team of 8 · 5G Academy, Federico II2026

Finding the root cause when a 5G network fails

One fault sets off alarms across a whole network, and a wrong confident answer is worse than an honest “not sure”. I owned the stage that names the failed element, or answers “investigate” when the evidence is weak.

Limit: Simulated networks only; the earlier ranker is a weak baseline on this test set.

Read the write-up

Experience

Data Scientist, Sakoudar

2022 to 2025 · full time · influencer campaign platform across LinkedIn, X and Instagram · one of two technical people

  • Built the scoring and recommendation engine behind the live platform; I owned the data, scoring and matching, and part of the backend.
  • Designed a cross-platform engagement score that corrects for posting frequency, audience size and category, and brand-fit matching with semantic text embeddings.
  • After launch, about 8 in 10 campaigns used the engine's recommendations instead of manual selection.
More about this role
  • The engagement score weights each interaction type per platform, using the platforms' own audience demographics.
  • Brand-fit matching compares each campaign's message and goals with influencers' own posts.
  • Applied sentiment analysis to influencer posts. Built the founders' review dashboard and the step that published approved scores to the live site.
  • Python, pandas, MySQL on the company server. Weekly data collection from three platform APIs, covering under 500 influencers.

Education

MSc Data Science, University of Naples Federico II

2023 to February 2027 (expected) · weighted average 28.67/30 · all exams finished, thesis in progress

BSc Information Technology Engineering, Amol University

Research

Research in progress

Thesis lab: PRISCA Lab ↗, University of Naples Federico II

No shieldreference
Standard shieldfrom the original paper
Adaptive shieldnew design
Firm or flexiblenew design
Study design
Study running
4
setups; every participant sees all four
  • Runs in the browser; the robot narrates each replay
  • No results yet; paper in preparation

MSc thesis · PRISCA Lab · supervised by Prof. Silvia Rossi

Making a learning robot readable to the person teaching it

People teach a learning robot a few movement rules, then watch it learn the same task four times under four setups and say which felt easiest to read and trust.

Limit: No results yet; a paper is being written from the study.

spec says
“Reset clears the counter.”
it does not say
rst active-high?
rst active-low?
so the model guesses
The question, by example
Paper in prep.
Code LLMs
what a model writing Verilog guesses when the spec is silent
  • With colleagues at the University of Bremen
  • Results not public yet

Paper in preparation · with colleagues at the University of Bremen

Code LLMs and the facts a hardware spec leaves out

When a spec does not say whether reset is active-high or active-low, a model writing Verilog has to guess. We measure which missing facts change the hardware it writes.

Limit: Results are not public yet.

5G simulator as a PettingZoo environment, KPI states
Agents per network element + an orchestrator
Reward: fast, correct isolation
Penalty: false alarms, extra actions
Research plan
Just starting
MARL
multi-agent RL that isolates root causes from network KPIs
  • Compared with rule-based and LLM approaches
  • A plan: nothing built or measured yet

Just starting · extends the 5G Academy root-cause work

Multi-agent reinforcement learning for 5G troubleshooting

Alarm timestamps mislead root-cause analysis: devices trip at different thresholds and faults spread asynchronously. The idea is to train distributed agents that isolate the root cause from network KPIs, coordinating with their neighbours and an orchestrator.

Limit: A research plan: nothing is built or measured yet.

More projects

6 more, from forecasting to data engineering

Cicalino 1
Cicalino 2
Imola 1
Imola 2
Imola 3
traintest
Catch days by trap, 6 Jul to 23 Aug 2024
Negative result
0.49
AUC once a leaking feature is removed (0.5 = guessing)
Leak0.92
Fixed0.49
Chance0.50

Live demoTeam of 3 · course project2025

Forecasting insect catches from weather and trap counts

Limit: The only data available was 49 days from 5 traps; once a leaking feature was removed, no model beat simple baselines.

Write-up
Training questions, word cloud
Live demo
0.202
validation loss after 3 epochs, 30,000 held-out questions
Epoch 10.240
Epoch 20.206
Epoch 30.202

Live demoTeam of 3 · course project2025

A vision-language model that answers questions about images

Limit: Only loss was measured; no accuracy score exists.

Write-up
Choropleth by district
Synthetic data
Per resident
store potential, so large and small districts compare fairly
  • Stores joined to districts by location
  • Public version runs on synthetic data

Team of 4 · Fater S.p.A. challenge2024

Store potential per resident, by district

Limit: The public map uses synthetic data; the real analysis is not public.

Write-up
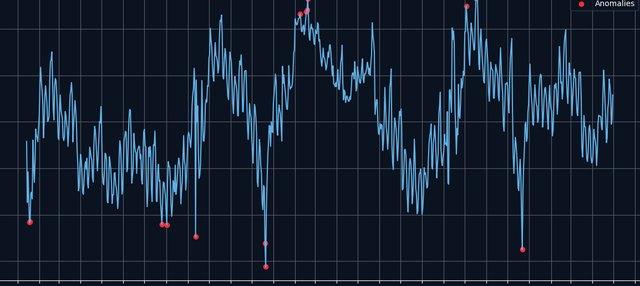
Daily clicks (log), unusual days in red
Case study
0.20
mean error on log daily clicks, last 20% of days held out
  • 1D CNN on 30-day windows
  • No simple baseline; only the CNN was scored

Team of 3 · course project2024

Forecasting daily student activity on a learning platform

Limit: Only the CNN was scored on the held-out days, and no simple baseline was run.

Write-up
silhouetteK = 4 chosenK = 2 to 10
Silhouette by K, read off the notebook's plot
Case study
6,875
daily price messages into 55 Kafka topics
  • K = 4 from silhouette and elbow plots
  • Clustering on one stock; nothing reads the topics

Team of 2 · course project2024

Stock prices through Kafka, clustered in PySpark

Limit: A one-off batch load, and K-means on one stock's 125 days of prices.

Write-up
Job ad (PDF, Word)
Gemini extracts skills
GitHub GraphQL search
Real profiles
Ranking unvalidated
System outline
Hackathon
24 h
prototype from job ad to ranked GitHub profiles
  • Parsing and search work
  • Ranking never checked; some inputs are placeholders

24-hour hackathon · team of 22025

TalentSonar: from a job ad to GitHub candidates

Limit: The candidate ranking was never validated, and years of experience are random placeholders.

Write-up

About

What ties the work together

The thread through my work is comparison: creators across platforms at Sakoudar, districts of very different sizes for Fater, nine routing methods under one safety layer. My newest work is in reinforcement learning, and my thesis asks how a learning robot can stay readable to the person who teaches it. I'm looking for a team that values clarity over cleverness and ships to real users, or a funded PhD in reinforcement learning or human-robot interaction. Strong in Python, SQL, PyTorch, Hugging Face Transformers, reinforcement learning, Apache Kafka and PySpark. Based in Naples and open to relocation. Languages: English C1, learning German (A1).